An API rate limit is not just a request counter. It is a rule that protects a particular resource, tied to an identity your server can trust, with a response clients can handle. A limit that counts the wrong thing or groups unrelated callers together can block legitimate users without preventing expensive work.
For a small service, start by deciding what you need to protect: fair access to an endpoint, a costly operation such as sending a text message, or the number of long-running jobs in progress. Those goals need different limits. This guide compares practical options and explains how to return useful HTTP responses, handle proxies, and test the policy.
Choose what to limit
Count the unit that corresponds to the cost or risk:
- Requests per identity and time period can help keep one account from dominating a shared API.
- Requests to a particular operation are useful when sign-in, password recovery, or sending a message has a different risk from reading a record.
- Concurrent work can protect an export, image conversion, or report endpoint whose requests remain active for a long time.
- Resource bounds such as maximum page size, upload size, execution time, and batch length limit work that a request can trigger.
A request limit alone does not bound the work inside a request. One allowed query might return thousands of records, trigger many database reads, or call a paid provider. The OWASP guidance on unrestricted resource consumption recommends combining rate limits with limits on inputs, operations, time, and third-party spending.
Compare the common algorithms
| Approach | How it works | Useful when | Trade-off |
|---|---|---|---|
| Fixed window | Count requests in a fixed time bucket, then reset the counter for the next bucket. | You want a simple, low-state rule. | A caller can use the allowance at the end of one window and again at the start of the next, creating a short burst. |
| Sliding-window log | Keep request timestamps and count those that fall within the most recent interval. | The boundary behavior needs to be precise and traffic per identity is modest. | Storing and pruning timestamps costs more memory and work as request volume grows. |
| Sliding-window counter | Combine counts from adjacent fixed windows to estimate the recent rolling total. | You want smoother boundaries without retaining every request. | It is an approximation, so it may not match an exact sliding log. |
| Token bucket | Refill a bucket at a configured rate; each request spends tokens, up to the bucket's capacity. | A normal average rate is important, but short bursts should be allowed. | The bucket capacity must be chosen deliberately because it defines the permitted burst. |
| Concurrency limit | Track active work and reject or queue requests after a maximum is reached. | Expensive operations occupy workers or connections for a long time. | It limits simultaneous work, not the total number of requests over a minute. |
The Redis rate-limiting tutorial demonstrates fixed and sliding windows, token buckets, and the trade-offs among them. It also explains why a shared counter's read, decision, and update need to be atomic: otherwise simultaneous requests can both see spare capacity and exceed the limit.
Do not add an elaborate algorithm by default. A fixed window may be sufficient for a small endpoint with low consequences at the boundary. Use a sliding approach if boundary bursts cause a real problem, and a token bucket if controlled bursts are part of the desired behavior. Add a concurrency limit separately for long-running work.
Choose an identity and policy
For authenticated requests, use a stable server-verified identity such as the account ID or API-key record. Do not use a username, query parameter, or other caller-controlled value as the only limiter key. API keys can help identify clients, but they can be copied or leaked; they are not authorization by themselves. OWASP's REST Security Cheat Sheet recommends returning 429 Too Many Requests when requests arrive too quickly and cautions against relying only on API keys for sensitive resources.
For anonymous traffic, an IP address may be one signal, but it is an imperfect identity: multiple people can share an address, and one person can use different addresses. Consider combining an IP-based ceiling with a per-account or per-operation policy when users sign in. Avoid making a high-impact decision from an identity a caller can cheaply change.
If a reverse proxy or CDN sits in front of the application, the socket address may be the proxy rather than the client. Only use forwarded IP headers when your application trusts the known proxy chain and that proxy removes or overwrites client-supplied forwarding headers. The Express guide to running behind proxies documents how an incorrect proxy trust setting can let a client influence the address the application sees.
Define separate rules where the risks differ. For example, a password-reset endpoint that sends a paid message needs tighter per-account and per-destination controls than a public read endpoint. A report-generation endpoint may need a small in-flight limit as well as a request-rate limit. Avoid choosing a single global number for every route without considering normal traffic, operation cost, and the effect on legitimate users.
Keep the limiter correct across instances
A counter stored in application memory applies only to one process. If requests are spread over several instances, each process may grant its own allowance; a restart may also clear its counters. That can be acceptable for a best-effort local safeguard, but it is not a shared API quota.
For a limit that must apply across instances, keep the state in a shared store and make the check-and-update atomic. Redis is one option; a database or gateway may be a better fit for an existing deployment. Measure the extra network dependency and decide what the API should do if the limiter store is unavailable. For a costly operation, failing closed or returning a service error may be safer than silently allowing unlimited work. For a low-risk read endpoint, availability may matter more. Make that choice explicit and alert on store failures.
An edge or gateway limit can reject obvious excess traffic before it reaches your application. Application-level limits can use authenticated identity and operation-specific rules. These layers complement each other; a gateway that sees only IP addresses cannot replace every account or business-level limit.
Return a useful 429 response
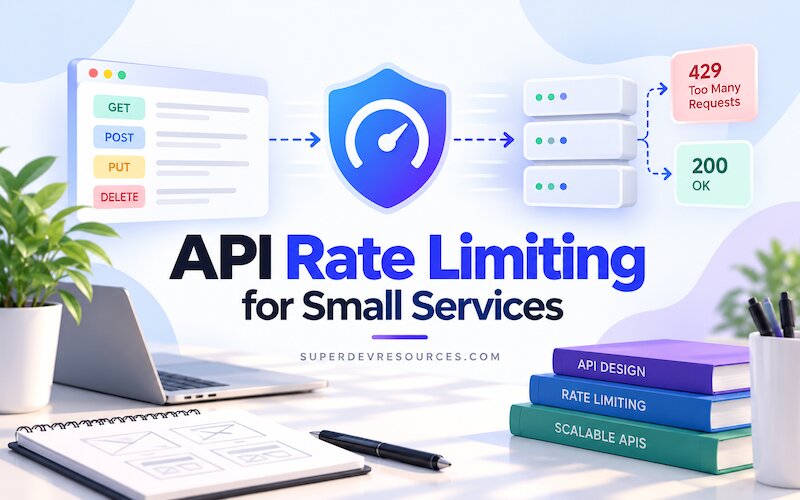
The HTTP 429 Too Many Requests status indicates that a client has sent too many requests in a period. RFC 6585 says the response should explain the condition, may include Retry-After, and must not be stored by a cache.
For a limit that will reset in 30 seconds, a response could look like this:
HTTP/1.1 429 Too Many Requests
Content-Type: application/json
Cache-Control: no-store
Retry-After: 30

{"error":"rate_limit_exceeded","message":"Wait before trying this operation again."}
Retry-After can be a number of seconds or an HTTP date, as described in MDN's header reference. Send a value your server can justify from the policy state; do not make clients guess when to try again. A brief explanation and a stable machine-readable error code also make it easier for clients to distinguish a quota response from a validation or authentication error.
Make clients back off safely
When a client receives 429, it should wait at least as long as Retry-After says before retrying. If the response has no usable retry value, use a bounded exponential backoff with random jitter rather than retrying immediately. Jitter prevents many clients from waking and retrying together.
Do not automatically repeat every request. A retry of an idempotent operation is different from replaying a payment, message send, or other request that may have already caused a side effect. For non-idempotent operations, use an idempotency key or another application-level deduplication mechanism before retrying after an uncertain result. See the HTTP method semantics in RFC 9110.
If your API has an OpenAPI description or request collection, document the 429 response and test its body and retry guidance alongside the success path. The guide to API testing and documentation workflows for small teams covers keeping API checks and docs aligned.
Monitor and tune the rule
Record enough information to tell whether a limit is protecting the service or frustrating legitimate callers:
- Which policy and route rejected the request.
- Whether the caller was authenticated, without logging its access token or raw API key.
- The number of allowed and rejected requests, plus the operation's latency and resource use.
- Limiter-store errors, timeouts, and any decision to fail open or closed.
Keep high-cardinality identities out of metric labels; aggregate metrics by route and policy, and restrict access to any detailed logs. Review rejected requests together with normal traffic before tightening a rule. Rate limiting is not a substitute for payload bounds, authorization, input validation, or abuse monitoring.
Test more than a single request sequence. Include requests at a window boundary, concurrent requests that arrive together, multiple application instances, authenticated and anonymous callers, and traffic through the actual proxy configuration. Also test that clients respect Retry-After and that the limit recovers after the expected interval. The secure-by-design programming guide offers related guidance for treating security checks as part of normal implementation and review.
A practical starting plan
For a small service, begin with a modest set of policies:
- Protect expensive or abuse-prone operations separately from ordinary reads.
- Use server-verified account or API-key identities for authenticated clients, with an IP-based safeguard for anonymous traffic.
- Pick the simplest algorithm that meets the desired burst behavior, and use a shared atomic store if a quota must span multiple instances.
- Return a clear
429with a usefulRetry-Aftervalue and an error body clients can parse. - Add concurrency, payload, pagination, timeout, and spending limits for work a request can trigger.
- Monitor rejections and test the policy under the proxy and deployment setup you actually use.
Start with the routes that have the greatest cost or abuse risk, then adjust the policy from observed behavior. A small, well-understood limiter is easier to operate than a complicated global rule whose identity, storage, and failure behavior are unclear.
